HolmesGPT
障害の原因を、ログを貼り付けさせるのではなく既存の監視基盤に自分で問い合わせて調べるエージェント
HolmesGPTとは
障害対応で時間がかかるのは修正ではなく、ダッシュボードを開き、急変をデプロイと突き合わせ、実際に落ちたポッドを見つけるまでの20分です。HolmesGPTはその部分を担います。すでに運用しているPrometheus、Grafana、Datadog、Kubernetes、任意のREST APIに接続し、必要なものを取得しては見つかった手がかりをたどる形で調査を進め、結論を元のアラートへ書き戻します。特徴的なのは、素朴な作りの道具が壊れる規模を前提にしている点です。絞り込みはサーバー側で行い、大きな出力はディスクへ流し、ツールごとにメモリ上限があるため、巨大な監視データを問い合わせても文脈が埋まったりプロセスが落ちたりしません。CNCFのサンドボックスプロジェクトです。
HolmesGPTで何ができますか?
- 貼り付けた抜粋ではなく生きたデータを調べる — すでに運用中の監視基盤へ問い合わせるため、誰かがたまたま貼り付けた内容ではなく現在の状態に基づいた答えが出ます。
- アラートの出所へ結論を書き戻す — AlertManagerやPagerDuty、OpsGenie、Jiraからアラートを読み、結論を書き戻します。調査結果がチャットではなくチケットに残ります。
- 大量の問い合わせに耐える — サーバー側での絞り込み、ツールごとのメモリ上限、大きな結果のディスクへの退避により、データ量の大きさで調査が破綻しません。
- 頼まれる前に見張る — 常駐モードでは定期的に、あるいはデプロイ後に稼働状態を確認し、人が気づく前に見つけたことを知らせます。
- Kubernetes以外も対象にする — 仮想マシン、クラウドサービス、データベース、SaaSにも接続できるため、コンテナ化しきっていない環境にも当てはまります。
- 未対応の情報源を足す — 任意のREST APIをツール群として登録できるので、社内独自の監視基盤があってもこの方式自体を諦める必要はありません。
HolmesGPTを選ぶ前に
- 届く範囲までしか働けません。有用な手がかりが誰も外に出していないダッシュボードや、文書化されていない社内システムにある環境では、接続を整えるまで役に立ちません。
- 常駐モード自体はKubernetes上で動くため、それ以外の基盤のチームは、依頼に応じた調査は使えても、無人の監視までは追加の作業なしには得られません。
よくある質問
HolmesGPTは商用利用できますか?
HolmesGPTはApache-2.0ライセンスで公開されています。OSI承認のオープンソースライセンスで、商用利用が認められています。
HolmesGPTはどの形で使えますか?
HolmesGPTはセルフホスト・ローカル実行の形で利用できます。
ドキュメント
HolmesGPT/holmesgpt のREADMEより転載(Apache-2.0)。 原文を読む ↗
Open-source AI agent for investigating production incidents and finding root causes. Works with any stack — Kubernetes, VMs, cloud providers, databases, and SaaS platforms. We are a Cloud Native Computing Foundation sandbox project. Originally created by Robusta.Dev, with major contributions from Microsoft.
New: Operator Mode — Find Problems 24/7 in the Background
Most AI agents are great at troubleshooting problems, but still need a human to notice something is wrong and trigger an investigation. Operator mode fixes that — HolmesGPT runs in the background 24/7, spots problems before your customers notice, and messages you in Slack with the fix. Connect the GitHub integration and it can even open PRs to fix what it finds.
While the operator itself runs in Kubernetes, health checks can query any data source Holmes is connected to — VMs, cloud services, databases, SaaS platforms, and more.
- Deployment verification — Deploy a health check alongside your app to verify the new version is healthy
- Scheduled health checks — Continuously monitor services and catch regressions automatically
Features
- Petabyte-scale data: Server-side filtering, JSON tree traversal, and tool output transformers keep large payloads out of context windows
- Memory-safe execution: Per-tool memory limits, streaming large results to disk, and automatic output budgeting prevent OOM kills when querying large observability datasets
- Deep integrations: Prometheus, Grafana, Datadog, Kubernetes, and many more—plus any REST API
- Bidirectional alert integrations: Fetch alerts from AlertManager, PagerDuty, OpsGenie, or Jira—and write findings back
- Any LLM provider: OpenAI, Anthropic, Azure, Bedrock, Gemini, and more
- No Kubernetes required: Works with any infrastructure — VMs, bare metal, cloud services, or containers
How it Works
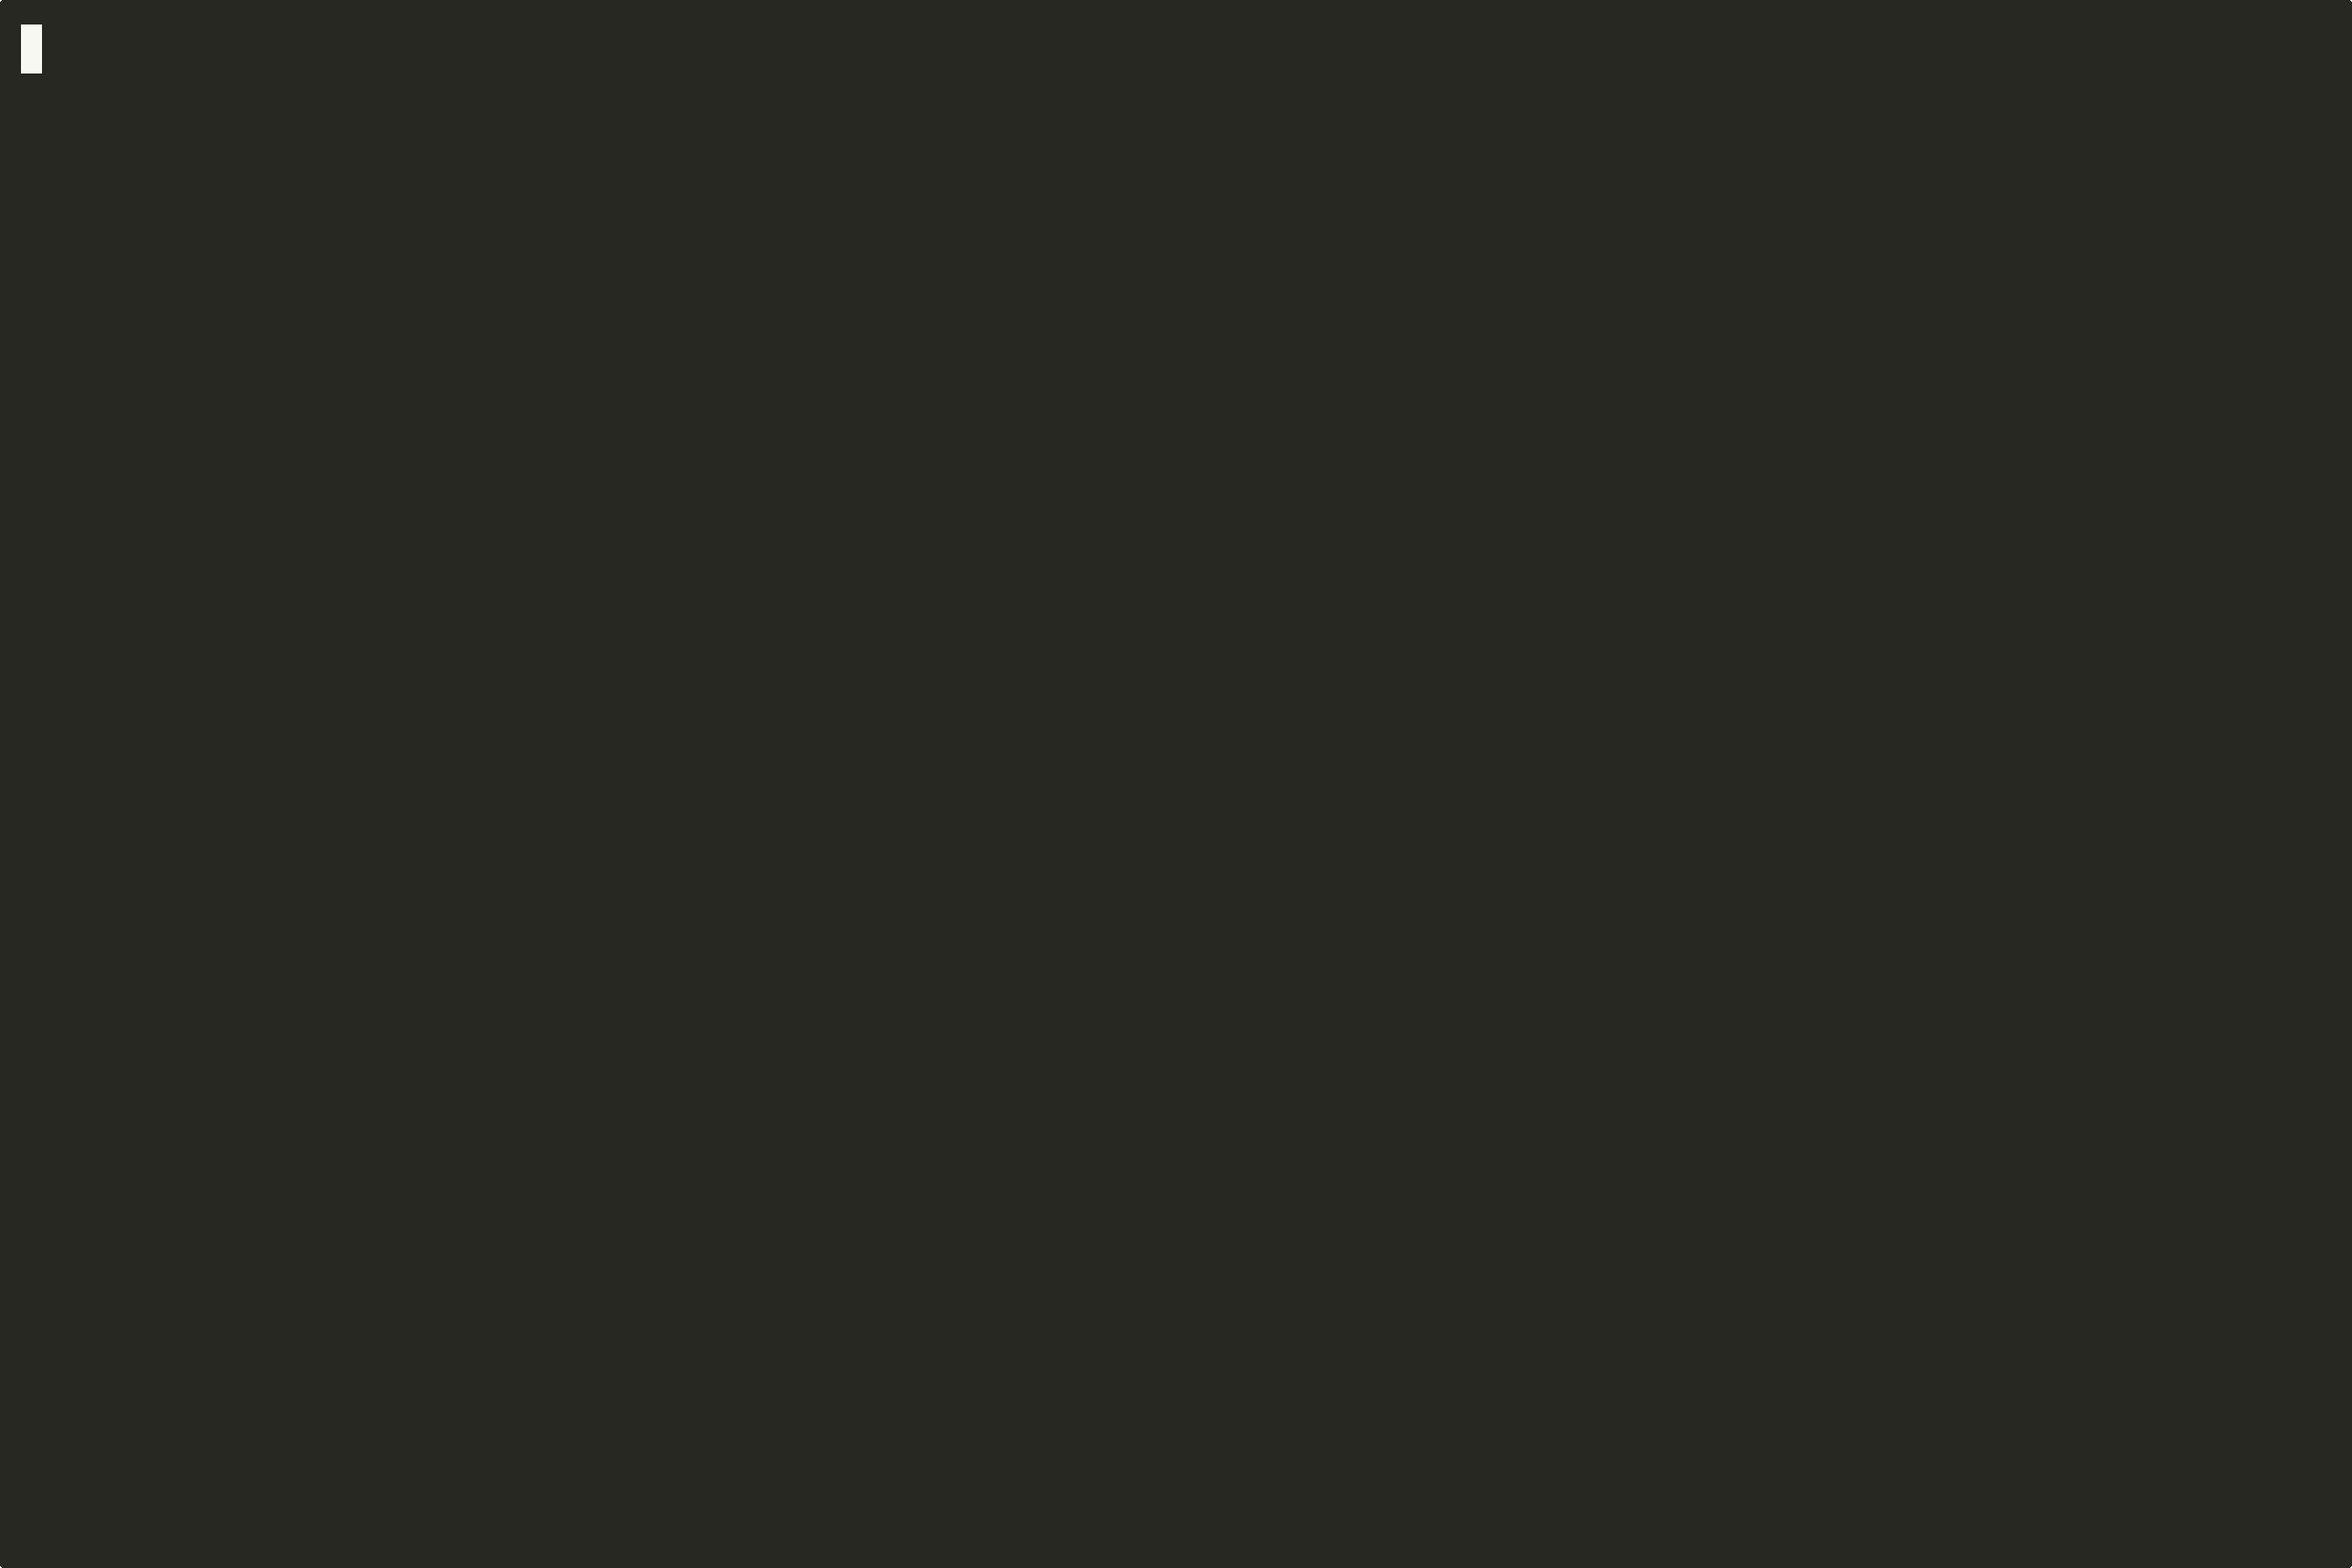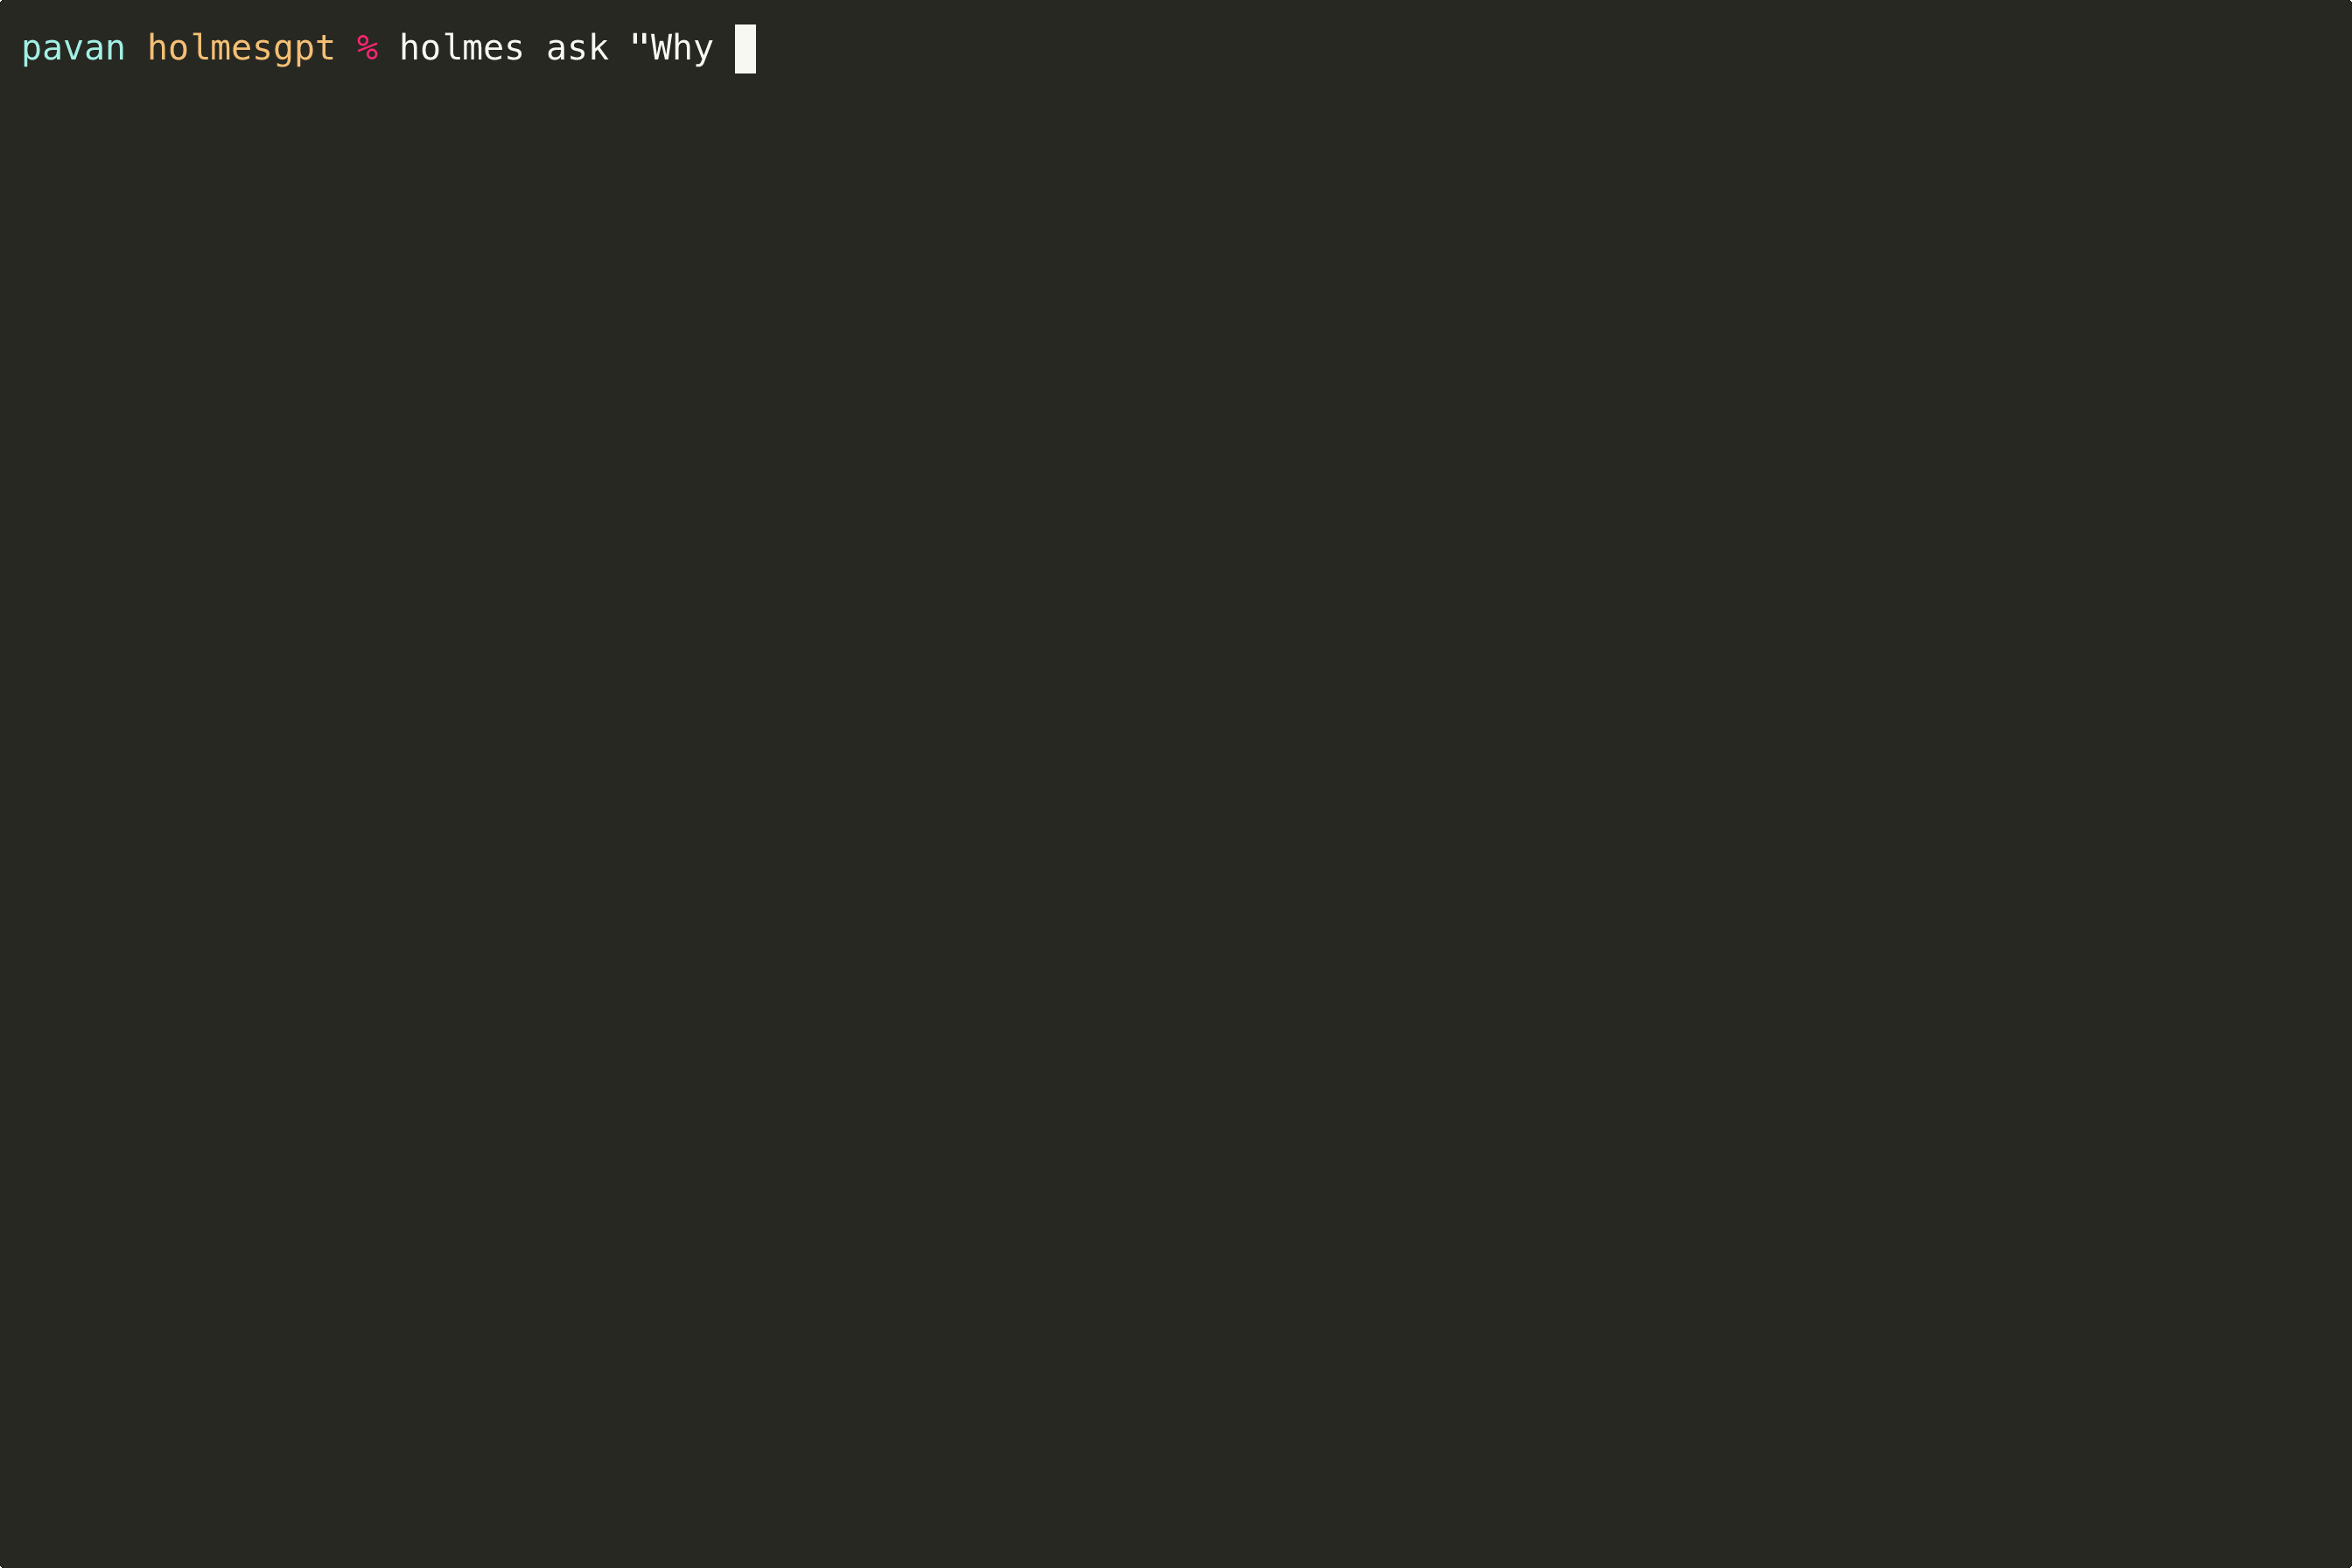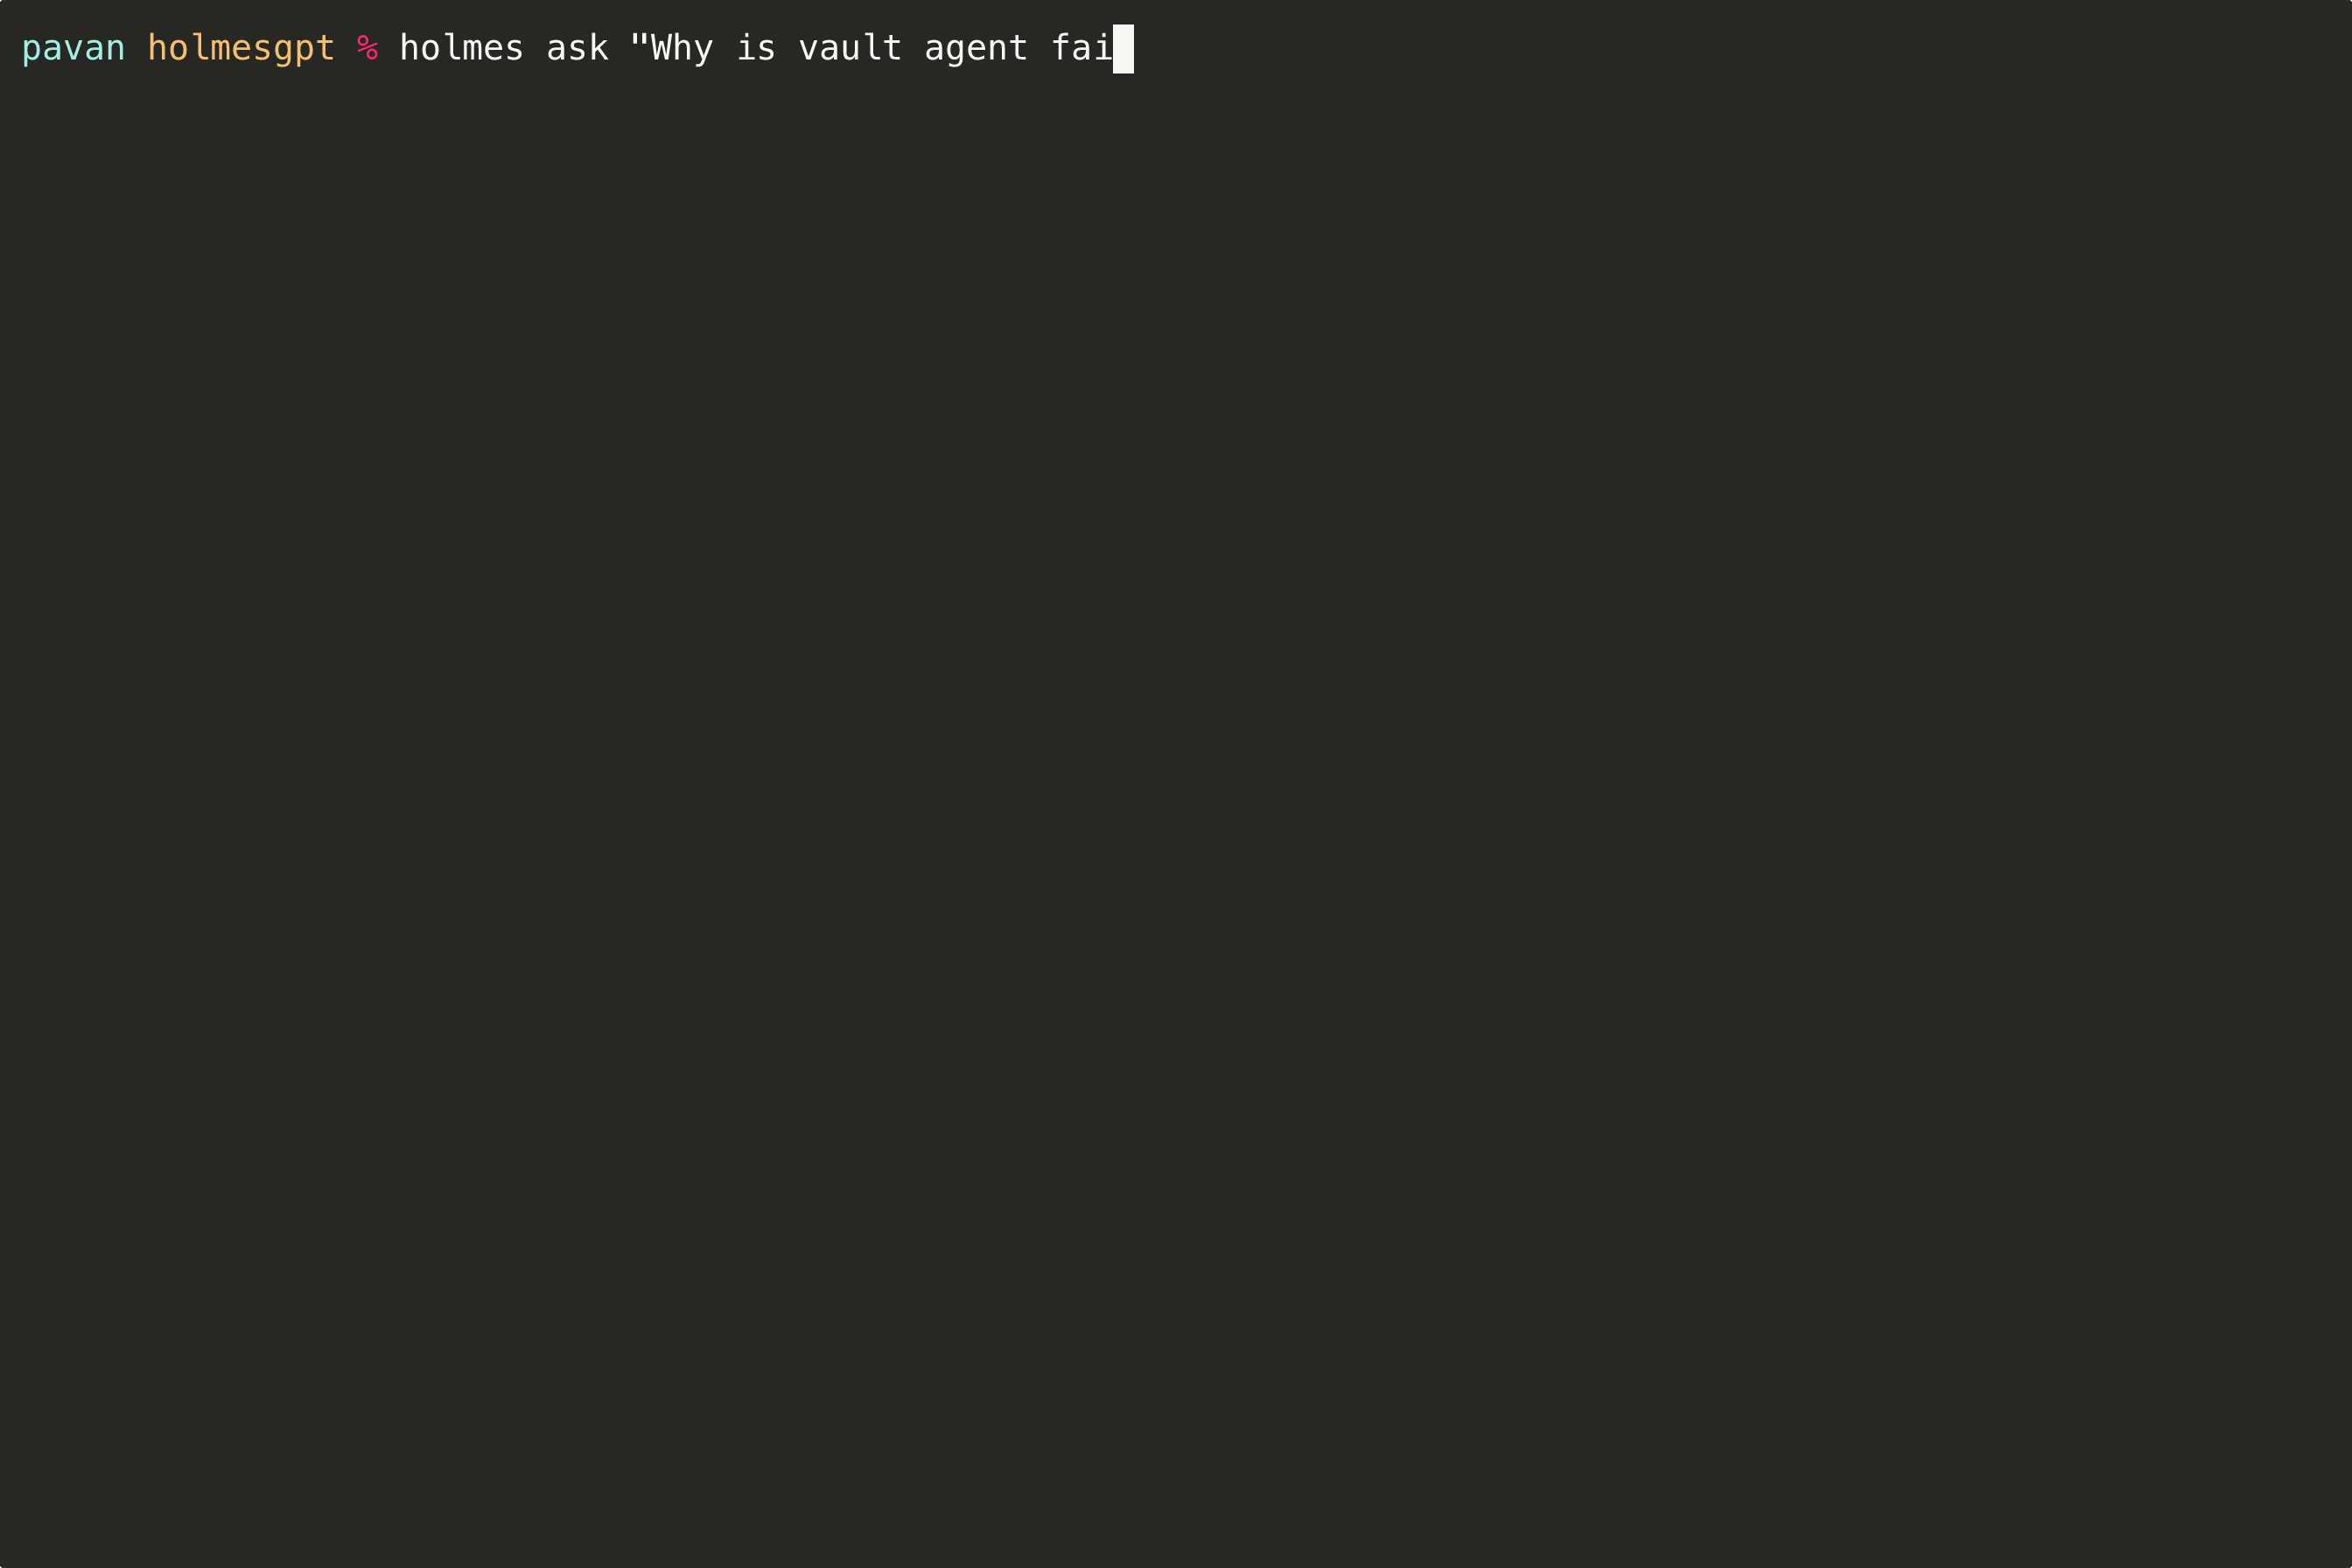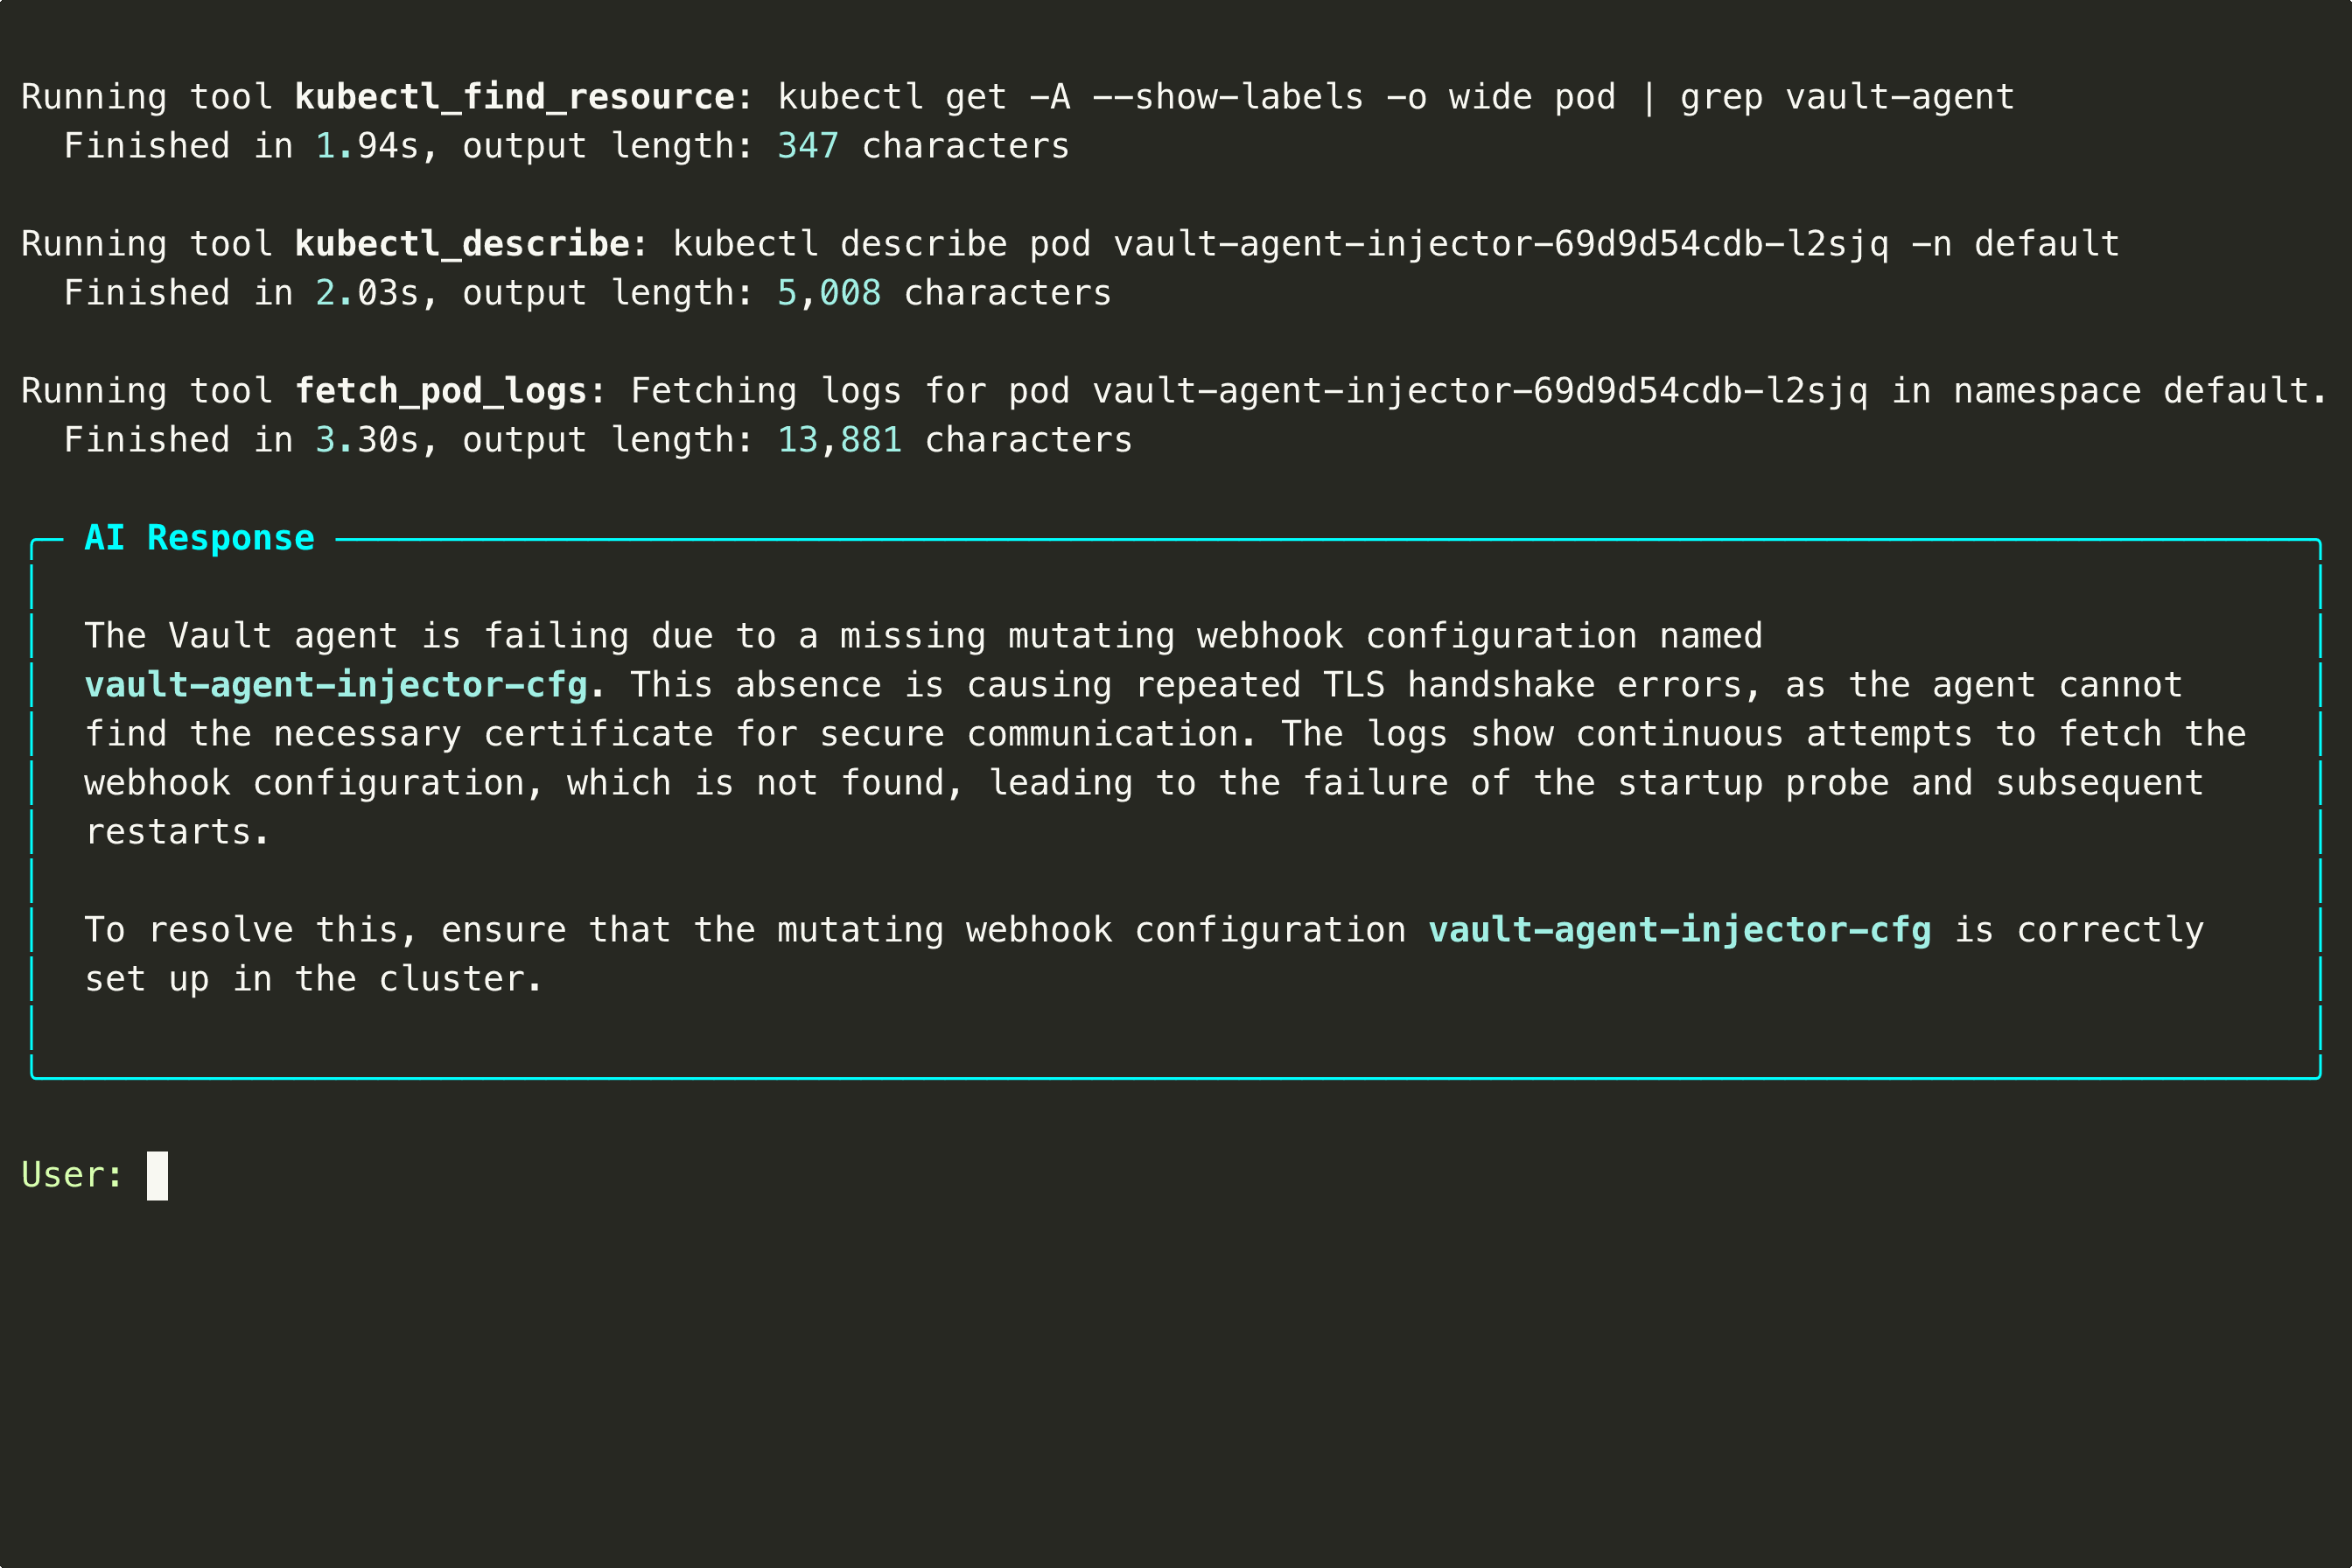
HolmesGPT uses an agentic loop to query live observability data from multiple sources and identify root causes.
🔗 Data Sources
HolmesGPT integrates with popular observability and cloud platforms. The following data sources (“toolsets”) are built-in. Add your own.
| Data Source | Notes |
|---|---|
| AKS | Azure Kubernetes Service cluster and node health diagnostics |
| Atlassian Rovo | Jira issues and Confluence pages via Atlassian’s hosted server (MCP) |
| ArgoCD | Get status, history and manifests and more of apps, projects and clusters |
| AWS | RDS events, instances, slow query logs, and more (MCP) |
| Azure | Azure resources and diagnostics (MCP) |
| Confluence | Private runbooks and documentation |
| Confluence (MCP) | Private runbooks and documentation (MCP) |
| Coralogix | Retrieve logs for any resource |
| Crossplane | Troubleshoot Crossplane providers, compositions, claims, and managed resources |
| Datadog | Query logs, metrics, and traces |
| Docker | Get images, logs, events, history and more |
| Elasticsearch / OpenSearch | Query logs, cluster health, shard and index diagnostics |
| GCP | Google Cloud Platform resources (MCP) |
| GitHub | Repositories, issues, and pull requests (MCP) |
| GitLab | Projects, merge requests, issues, and CI/CD pipelines (MCP) |
| Jenkins (MCP) | Build status, pipeline logs, and job history (MCP) |
| Grafana | Query and analyze dashboard configurations and panels |
| Helm | Release status, chart metadata, and values |
| Internet | Public runbooks, community docs, etc. |
| Kafka | Fetch metadata, list consumers and topics or find lagging consumer groups |
| Kubernetes | Pod logs, K8s events, and resource status (kubectl describe) |
| Kubernetes Remediation (MCP) | Apply fixes like scaling, rollbacks, and resource edits (MCP) |
| Loki | Query logs for Kubernetes resources or any query |
| MariaDB | MariaDB database queries and diagnostics |
| MongoDB | Query data, diagnose performance, inspect schemas, find slow operations |
| MongoDB Atlas | Cluster health, slow queries, and performance diagnostics |
| NewRelic | Investigate alerts, query tracing data |
| OpenShift | Projects, routes, builds, security context constraints, and deployment configs |
| Prefect (MCP) | Workflow orchestration monitoring, flow runs, and worker health (MCP) |
| Prometheus | Investigate alerts, query metrics and generate PromQL queries |
| RabbitMQ | Partitions, memory/disk alerts, troubleshoot split-brain scenarios and more |
| Robusta | Multi-cluster monitoring, historical change data, runbooks, PromQL graphs and more |
| ServiceNow | Query tables and incident records |
| Sentry | Error tracking, issues, and performance monitoring (MCP) |
| Slab | Team knowledge base and runbooks on demand |
| Splunk | Log search and analysis (MCP) |
| SQL Databases | PostgreSQL, MySQL, ClickHouse, MariaDB, SQL Server, Azure SQL, SQLite |
| Tempo | Fetch trace info, debug issues like high latency in application |
| VictoriaLogs | Query logs from VictoriaLogs using LogsQL |
| VictoriaMetrics | Query metrics from a Prometheus-compatible TSDB (vmsingle / vmcluster) |
| Zabbix | Monitor hosts, problems, events, triggers, and historical metrics |
See the full list of built-in toolsets for additional integrations including Cilium, KubeVela, Notion, and more.
🚀 End-to-End Automation
HolmesGPT can fetch alerts/tickets to investigate from external systems, then write the analysis back to the source or Slack.
| Integration | Status | Notes |
|---|---|---|
| Slack | ✅ | Demo. Available via Robusta |
| Microsoft Teams | ✅ | Available via Robusta |
| Prometheus/AlertManager | ✅ | Robusta or HolmesGPT CLI |
| PagerDuty | ✅ | HolmesGPT CLI only |
| OpsGenie | ✅ | HolmesGPT CLI only |
| Jira | ✅ | HolmesGPT CLI only |
| GitHub | ✅ | HolmesGPT CLI only |
Installation
Read the installation documentation to learn how to install HolmesGPT.
Supported LLM Providers
Read the LLM Providers documentation to learn how to set up your LLM API key.
Using HolmesGPT
See the walkthrough documentation for usage guides, including:
- Interactive mode for asking questions and follow-ups
- Investigating Prometheus alerts
- CI/CD troubleshooting
🔐 Data Privacy
By design, HolmesGPT has read-only access and respects RBAC permissions. It is safe to run in production environments.
Community
Join our community to discuss the HolmesGPT roadmap and share feedback:
Support
If you have any questions, feel free to message us on HolmesGPT Slack Channel
How to Contribute
Please read our CONTRIBUTING.md for guidelines and instructions.
For help, contact us on Slack or ask DeepWiki AI your questions.
Please make sure to follow the CNCF code of conduct - details here.
ツール連携の他の選択肢
 openclawツール連携
`openclaw onboard --install-daemon`で手元のマシンにGatewayを常駐させると、セッション、ツール、イベント、チャネル接続がそこへ集約され、Control UI、CLI、TUI、接続済みのメッセージングチャネルが同じアシスタントを共有します。モデルはホスト型でもローカルでも構成でき、機能追加は本体の改造ではなくplugin SDKで作るプラグインを前提としています。一方で想定利用者は単独のオペレーターで、メインセッションのツールはサンドボックスを明示的に設定しない限りホスト上でそのまま実行され、DM可能なチャネルでは受信メッセージを未信頼の入力として扱う前提になっています。他のユーザーを参加させたりGatewayを外部へ公開したりする構成は、README自体がsecurityとsandboxingのガイドを先に読むよう促している領域であり、チームでの共有運用を第一に考えるなら選択肢から外れます。
 hermes-agentツール連携
Nous Research自身が開発するエージェント本体で、TUIと単一のgatewayプロセスがTelegram、Discord、Slack、WhatsApp、Signal、Emailの会話を束ね、cronスケジューラ、隔離されたサブエージェント、local/Docker/SSH/Singularity/Modal/Daytona/Vercel Sandboxという7種類のターミナルバックエンドを備えます。核になるのは閉じた学習ループで、定期的な促しに応じて記憶を整理し、複雑なタスクの後に自らスキルを作り、FTS5とLLM要約で過去セッションを検索します。裏を返せば、有用さの源である状態が`~/.hermes`配下に溜まり続け、バージョン管理の外で育つため、定期的な棚卸しが前提になります。組み込み用のライブラリではなく運用するアシスタントであり、READMEが記載するのはhermesのサブコマンドとスラッシュコマンドで、埋め込み用のAPIではありません。自作コードから呼ぶエージェントループが欲しい用途には向きません。シェルを扱えるエージェントをチャット経由で露出させる以上、コマンド承認とDMペアリングの設定は任意の飾りではなくなります。
 n8nワークフロー
数百のサービスをつなぐ処理をワークフローとして画面上で組み立てる自動化ツールです。流れの中の1つ1つの処理はノードと呼ばれ、近年はAIエージェントをノードとしてワークフローに組み込む使い方が増えています。最初に確認すべきはライセンスです。OSI承認のオープンソースではなく、Sustainable Use Licenseによるソース公開型にあたります。社内利用やセルフホストは可能ですが、ホスティングサービスとして再販することは認められていません。