AgentBench
モデルをエージェントとして測る。問答集ではなく、シェル、データベース、買い物サイトの中に置いて成否を見る
AgentBenchとは
うまく答えられるモデルが、何かを操作させると使い物にならないことはあります。問答形式のベンチマークではそれが見えません。AgentBenchは、反応が返ってくる環境の中にモデルを置きます。作業しなければならないシェル、問い合わせを組み立てるデータベース、知識グラフ、テキストの世界、そして正しい商品が注文されて初めて成功となる買い物サイトです。採点の基準は課題を達成できたかどうかで、推論の読みやすさではありません。現行版はこれらの環境をコンテナとして動かし、関数呼び出し形式で操作させるため、自前の機材で再現できます。ただし公開されている実務上の注意もあり、約16GBのメモリを要する環境や、ワーカーを再起動するまで資源を消費し続ける環境が含まれます。
AgentBenchで何ができますか?
- 文章のうまさではなく達成を採点する — データベースが正しい行を返したか、正しい商品が注文されたかで判定します。もっともらしい回答よりはるかに厳しい基準です。
- 性質の異なる操作を一度に扱う — シェル作業、データベースの問い合わせ、知識グラフの探索、テキストの世界、Webでの買い物は、それぞれ違う形で失敗します。弱点の出方が見えます。
- 自分の環境で再現する — 各環境はコンテナとして提供され、1つのコマンドで起動します。比較のために外部の順位表に頼る必要がありません。
- 実際に使う関数呼び出しの経路で測る — 現行版は自由文の解析ではなく関数呼び出しでモデルを動かすため、測っているのは本番コードが使うのと同じ接続方法です。
- 実行規模に応じてワーカーを増やす — 各環境は独立したワーカーとして動き、複製できます。長い評価をマシンの資源に広げて実行できます。
AgentBenchを選ぶ前に
- 運用上の粗さが公式に記されています。起動に約16GBのメモリを要する環境、ワーカーを再起動するまでメモリとディスクを消費し続ける環境、別途データを入手する必要がある環境があります。
- 現行の関数呼び出し版は初期版と課題の構成が異なるため、公表値を比較できるのは同じ版どうしに限られます。スコアを見るときはどの版のものかを確認してください。
よくある質問
AgentBenchは商用利用できますか?
AgentBenchはApache-2.0ライセンスで公開されています。OSI承認のオープンソースライセンスで、商用利用が認められています。
AgentBenchはどの形で使えますか?
AgentBenchはローカル実行・セルフホストの形で利用できます。
ドキュメント
THUDM/AgentBench のREADMEより転載(Apache-2.0)。 原文を読む ↗
AgentBench
🔥[2025.10.10] Introducing AgentBench FC (Function Calling) based on AgentRL
The current repository contains the function-calling version of AgentBench, integrated with AgentRL, an end-to-end multitask and mutliturn LLM Agent RL framework. If you wish to use the older version, you can revert to v0.1 and v0.2.
Comparing to the original AgentBench, this version uses a function-calling style prompt, and adds fully-containerized deployment support for the following tasks:
alfworld(AF)dbbench(DB)knowledgegraph(KG)os_interaction(OS)webshop(WS)
Quick Start
We support a quick one-command setup for all the above tasks using Docker Compose.
Before starting, please download or build the following Docker images required by the tasks:
# dbbench
docker pull mysql:8

# os_interaction
docker build -t local-os/default -f ./data/os_interaction/res/dockerfiles/default data/os_interaction/res/dockerfiles
docker build -t local-os/packages -f ./data/os_interaction/res/dockerfiles/packages data/os_interaction/res/dockerfiles
docker build -t local-os/ubuntu -f ./data/os_interaction/res/dockerfiles/ubuntu data/os_interaction/res/dockerfiles
To run the KG freebase server, you will also need a copy of the data found here.
Download, extract and place the data at ./virtuoso_db/virtuoso.db (or modify extra/docker-compose.yml and set the mount point to your data location).
Then, you can bring up the stack with:
docker compose -f extra/docker-compose.yml upThis command will download or build the necessary Docker images and start the following services in Docker:
- AgentRL Controller
alfworldtask worker (x1, increase as needed)dbbenchtask worker (x1, increase as needed)knowledgegraphtask worker (x1, increase as needed)os_interactiontask worker (x1, increase as needed)webshoptask worker (x1, increase as needed)- freebase server (for
knowledgegraphtask) - Redis server (for container allocation)
If your machine already has Redis (version 7+) running, you can omit the Redis service from the docker-compose.yml.
[!WARNING]
Please note that thewebshopenvironment requires ~16GB of RAM to start, and the current implementation ofalfworldleaks memory and disk space until the task worker is restarted. Make sure your machine has sufficient resources before running.
Benchmarking Results
We report the results of various models on the test set of AgentBench FC.
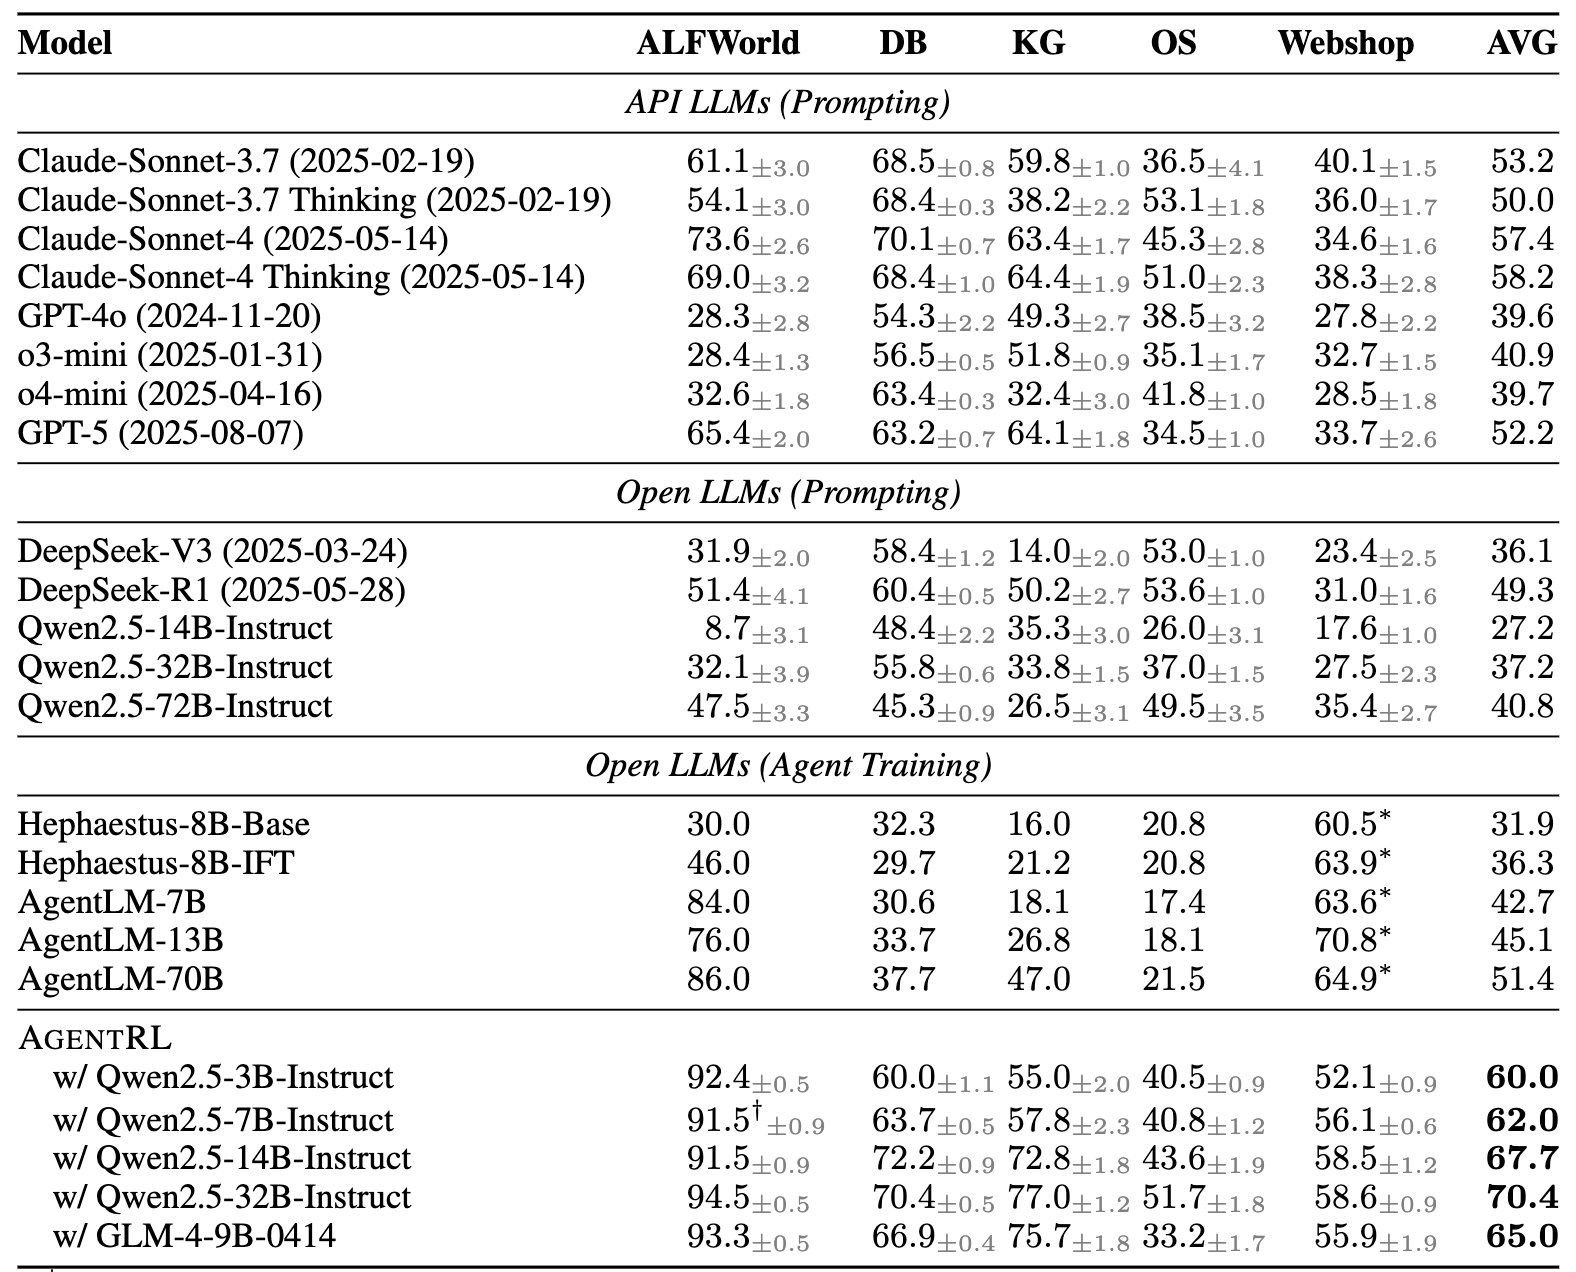
Please see our Leaderboard for full results. Please contact agentbench_fc@googlegroups.com if you have any questions or would like to contribute your results.
🔥[2024.08.13] Introducing VisualAgentBench
VisualAgentBench is designed for evaluating and training visual foundation agents based on large multimodel models (LMMs). We introduce 5 distinct environments spanning
- Embodied: VAB-OmniGibson, VAB-Minecraft
- GUI: VAB-Mobile, VAB-WebArena-Lite
- Visual Design: VAB-CSS
to systematically benchmark 17 LMMs (proprietary & open LMMs). We also provide the trajectory dataset for behavior cloning training on open LMMs for you to develop your own visual foundation agents!
The following is the introduction to the original AgentBench (v0.2).
AgentBench: Evaluating LLMs as Agents
https://github.com/THUDM/AgentBench/assets/129033897/656eed6e-d9d9-4d07-b568-f43f5a451f04
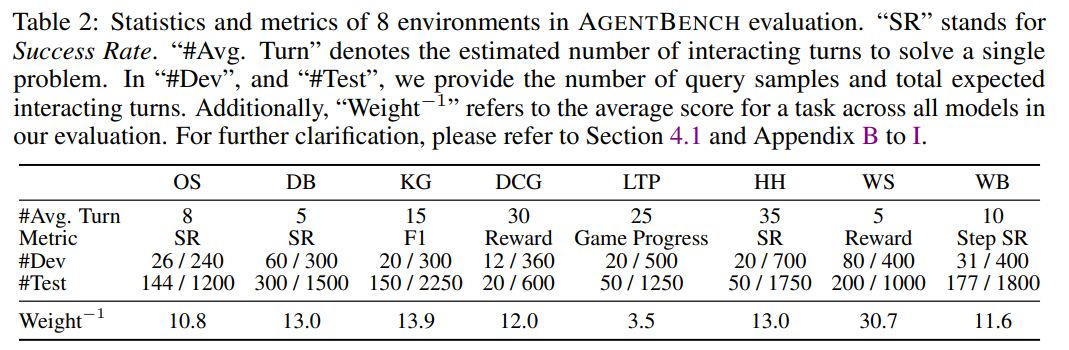
AgentBench is the first benchmark designed to evaluate LLM-as-Agent across a diverse spectrum of different environments. It encompasses 8 distinct environments to provide a more comprehensive evaluation of the LLMs’ ability to operate as autonomous agents in various scenarios. These environments include 5 freshly created domains, namely
- Operating System (OS)
- Database (DB)
- Knowledge Graph (KG)
- Digital Card Game (DCG)
- Lateral Thinking Puzzles (LTP)
as well as 3 recompiled from published datasets:
Table of Contents
Dataset Summary
We offer two splits for each dataset: Dev and Test. The multi-turn interaction requires an LLMs to generate around 4k and 13k times respectively.
Leaderboard
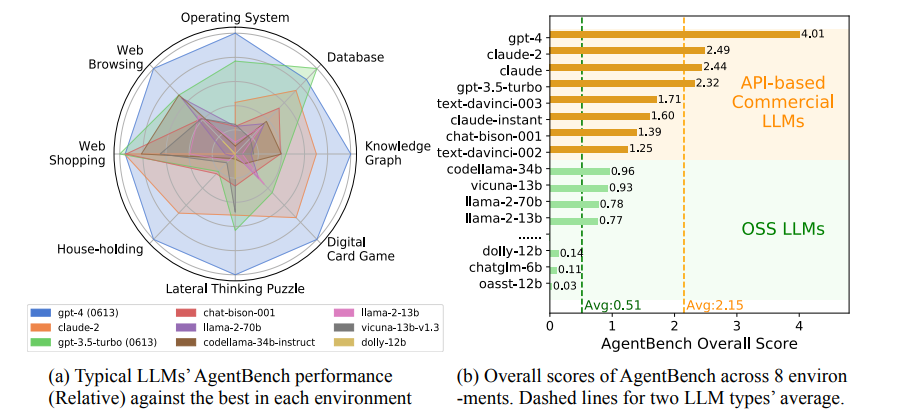
Here is the scores on test set (standard) results of AgentBench.
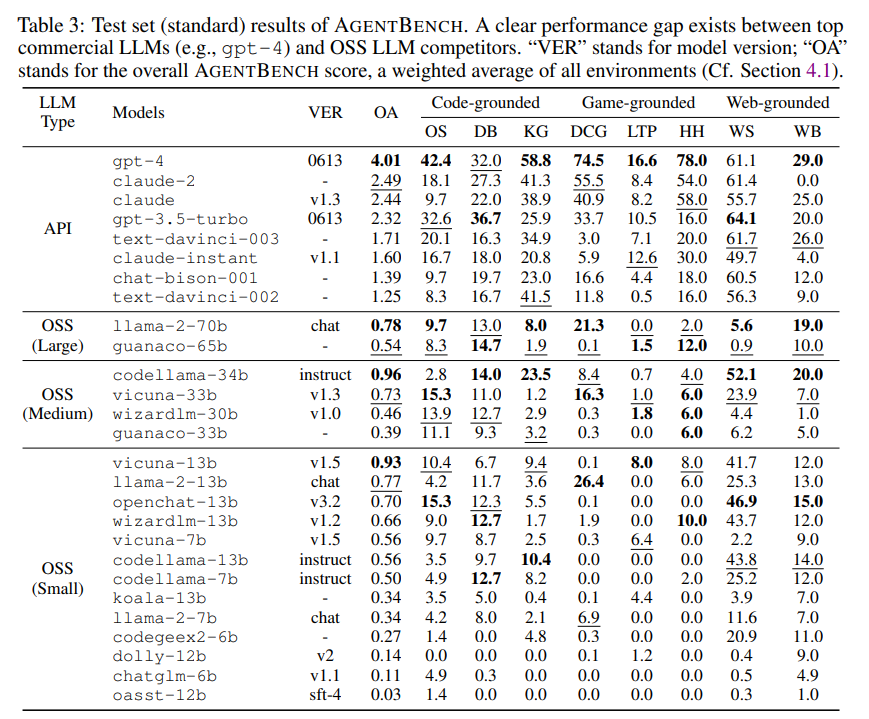
While LLMs begin to manifest their proficiency in LLM-as-Agent, gaps between models and the distance towards practical usability are significant.
Quick Start
This section will guide you on how to quickly use gpt-3.5-turbo-0613 as an agent to launch the dbbench-std and os-std tasks.
For the specific framework structure, please refer to Framework Introduction.
For more detailed configuration and launch methods, please check Configuration Guide
and Program Entrance Guide.
Step 1. Prerequisites
Clone this repo and install the dependencies.
Python version note: AgentBench pins older scientific Python deps (e.g.
numpy~=1.23.x). Using the recommended Python 3.9 (via conda) is the most reliable way to install dependencies.
cd AgentBench
conda create -n agent-bench python=3.9
conda activate agent-bench
pip install -r requirements.txt
Ensure that Docker is properly installed.
docker psBuild required images for dbbench-std and os-std.
docker pull mysql
docker pull ubuntu
docker build -f data/os_interaction/res/dockerfiles/default data/os_interaction/res/dockerfiles --tag local-os/default
docker build -f data/os_interaction/res/dockerfiles/packages data/os_interaction/res/dockerfiles --tag local-os/packages
docker build -f data/os_interaction/res/dockerfiles/ubuntu data/os_interaction/res/dockerfiles --tag local-os/ubuntu
Step 2. Configure the Agent
Fill in your OpenAI API Key at the correct location in configs/agents/openai-chat.yaml. (e.g. gpt-3.5-turbo-0613)
You can try using python -m src.client.agent_test to check if your agent is configured correctly.
By default, gpt-3.5-turbo-0613 will be started. You can replace it with other agents by modifying the parameters:
python -m src.client.agent_test --config configs/agents/api_agents.yaml --agent gpt-3.5-turbo-0613Step 3. Start the task server
Starting the task worker involves specific tasks. Manual starting might be cumbersome; hence, we provide an automated script.
The assumption for this step is that ports from 5000 to 5015 are available. For Mac OS system, you may want to follow here to free port 5000 to use.
python -m src.start_task -aThis will launch five task_workers each for dbbench-std and os-std tasks and automatically connect them
to the controller on port 5000. After executing this command, please allow approximately 1 minute for the task setup to complete. If the terminal shows ”… 200 OK”, you can open another terminal and follow step 4.
Lite preset (laptops / limited RAM)
If you want to start with minimal concurrency (1 worker per task), use the lite preset:
python -m src.start_task -a --config configs/start_task_lite.yamlStep 4. Start the assigner
This step is to actually start the tasks.
If everything is correctly configured so far, you can now initiate the task tests.
python -m src.assignerIf you started the task server with the lite preset, you can also run the lite evaluation preset:
python -m src.assigner --config configs/assignments/lite.yamlNext Steps
If you wish to launch more tasks or use other models, you can refer to the content in Configuration Guide and Program Entrance Guide.
For the environment of the remaining five tasks, you will need to download the Docker images we provide.
longinyu/agentbench-ltp
longinyu/agentbench-webshop
longinyu/agentbench-mind2web
longinyu/agentbench-card_game
longinyu/agentbench-alfworld
The resource consumption of a single task_worker for the eight tasks is roughly as follows; consider this when launching:
| Task Name | Start-up Speed | Memory Consumption |
|---|---|---|
| webshop | ~3min | ~15G |
| mind2web | ~5min | ~1G |
| db | ~20s | < 500M |
| alfworld | ~10s | < 500M |
| card_game | ~5s | < 500M |
| ltp | ~5s | < 500M |
| os | ~5s | < 500M |
| kg | ~5s | < 500M |
Deploy the KnowledgeGraph service loacally
the KnowledgeGraph task depends on an online service which now is not stable, if you want to deploy the service locally, you can follow steps below:
step1. download the database and setup the service freebase-setup.
step2.
change this line sparql_url: "http://164.107.116.56:3093/sparql" to sparql_url: "<your service api of sparql>" in /configs/tasks/kg.yaml.
P.S. you should start your KG service before you start the agent tasks services.
Extending AgentBench
If you wish to add new tasks to AgentBench, you may refer to Extension Guide.
References
Avalon task is merged from AvalonBench, which implements a multi-agent framework.
ベンチマーク / データセットの他の選択肢
 promptfoo可観測性
テストケースはYAMLです。プロンプト、いくつかの入力、そして出力に対する表明を書きます。それだけで、同じ入力に対して複数のプロンプトやモデルを並べた比較表が得られ、変更で品質が下がったときにビルドを失敗させられます。同じツールがアプリケーションへの攻撃も行い、敵対的な入力を生成して脆弱性やコンプライアンス上のリスクを洗い出します。ただし外側から、プロンプトを入れて回答を見る形で動きます。稼働中のエージェントのどの段階で問題が起きたかを知りたい場合、この道具は向きません。
 DeepEval可観測性
形は意図的にpytestそのものです。テスト関数の中に表明を書き、それを発見して実行するランナーがあり、引数を変えたケースも書けます。違うのは、表明の対象が「回答が文脈に忠実だったか」「エージェントがタスクを完了したか」である点です。この形にした狙いは明確で、品質の劣化を、構文エラーを捕まえるのと同じ関門の前に持ち込むことにあります。想定しておくべきなのは、これらの指標の多くがモデルによって採点されることです。通常のテストには無い費用とばらつきが伴います。
 camelマルチエージェント制御
CAMELは、エージェント同士に会話をさせることを出発点にした研究寄りのライブラリです。RolePlayingは指示を出す側と実行する側の2つのエージェントを組ませ、Workforceでは調整役が分割したサブタスクを複数の作業者へ配ります。その周囲には、80を超えるツール群、約50のモデル接続、GAIAやBrowseCompなどのベンチマーク実行環境、対話の記録を微調整用データセットへ変換するパイプラインが揃っています。実験を回す用途ならこの幅広さ自体が強みですが、本番で1つのエージェントを堅実に動かしたいだけなら使わない部分を大量に抱え込むことになりますし、2023年の公開以来バージョンは0.2系のままです。