AgentBench
Measures a model as an agent by putting it in a shell, a database and a shopping site, not in a question-and-answer set
What is AgentBench?
A model that answers well can still be poor at operating something, and a question-and-answer benchmark will not show that. AgentBench puts a model into environments that push back: a shell it has to work in, a database it has to query, a knowledge graph, a text world and a shopping site where the task only counts if the right item ends up ordered. Every task is scored on whether it was completed, not on whether the reasoning read well. The current release runs those environments as containers driven by function calling, which makes it reproducible on your own hardware — with the practical caveats the maintainers list, including one environment that needs about 16GB of memory and another that leaks until its worker is restarted.
What can you do with AgentBench?
- Score completion, not eloquence — A task counts when the database returned the right rows or the right item was ordered, which is a harder bar than a plausible-looking answer.
- Cover several kinds of operating at once — Shell work, database queries, knowledge-graph navigation, a text world and web shopping each fail differently, so the set exposes different weaknesses.
- Reproduce it on your own machine — The environments ship as containers brought up with a single compose command, so a comparison does not depend on a hosted leaderboard.
- Test the function-calling path you actually use — The current version drives models through function calling rather than parsed free text, so what is measured is the interface production code uses.
- Scale the workers to the run — Each environment runs as its own worker that can be replicated, so a long evaluation can be spread across more of the machine.
Before you choose AgentBench
- The maintainers document real operational rough edges: one environment needs roughly 16GB of memory, another leaks memory and disk until its worker is restarted, and a third needs a separately downloaded dataset.
- The current function-calling release covers a different task set from the original versions, so published numbers are only comparable within the same version — check which one a score refers to.
Frequently asked questions
Is AgentBench free for commercial use?
AgentBench is released under the Apache-2.0 licence — OSI-approved open source, which permits commercial use.
How can AgentBench be deployed?
AgentBench is available as Runs locally / Self-hosted.
Documentation
Reproduced from the THUDM/AgentBench README, published under Apache-2.0. Read the original ↗
AgentBench
🔥[2025.10.10] Introducing AgentBench FC (Function Calling) based on AgentRL
The current repository contains the function-calling version of AgentBench, integrated with AgentRL, an end-to-end multitask and mutliturn LLM Agent RL framework. If you wish to use the older version, you can revert to v0.1 and v0.2.
Comparing to the original AgentBench, this version uses a function-calling style prompt, and adds fully-containerized deployment support for the following tasks:
alfworld(AF)dbbench(DB)knowledgegraph(KG)os_interaction(OS)webshop(WS)
Quick Start
We support a quick one-command setup for all the above tasks using Docker Compose.
Before starting, please download or build the following Docker images required by the tasks:
# dbbench
docker pull mysql:8

# os_interaction
docker build -t local-os/default -f ./data/os_interaction/res/dockerfiles/default data/os_interaction/res/dockerfiles
docker build -t local-os/packages -f ./data/os_interaction/res/dockerfiles/packages data/os_interaction/res/dockerfiles
docker build -t local-os/ubuntu -f ./data/os_interaction/res/dockerfiles/ubuntu data/os_interaction/res/dockerfiles
To run the KG freebase server, you will also need a copy of the data found here.
Download, extract and place the data at ./virtuoso_db/virtuoso.db (or modify extra/docker-compose.yml and set the mount point to your data location).
Then, you can bring up the stack with:
docker compose -f extra/docker-compose.yml upThis command will download or build the necessary Docker images and start the following services in Docker:
- AgentRL Controller
alfworldtask worker (x1, increase as needed)dbbenchtask worker (x1, increase as needed)knowledgegraphtask worker (x1, increase as needed)os_interactiontask worker (x1, increase as needed)webshoptask worker (x1, increase as needed)- freebase server (for
knowledgegraphtask) - Redis server (for container allocation)
If your machine already has Redis (version 7+) running, you can omit the Redis service from the docker-compose.yml.
[!WARNING]
Please note that thewebshopenvironment requires ~16GB of RAM to start, and the current implementation ofalfworldleaks memory and disk space until the task worker is restarted. Make sure your machine has sufficient resources before running.
Benchmarking Results
We report the results of various models on the test set of AgentBench FC.
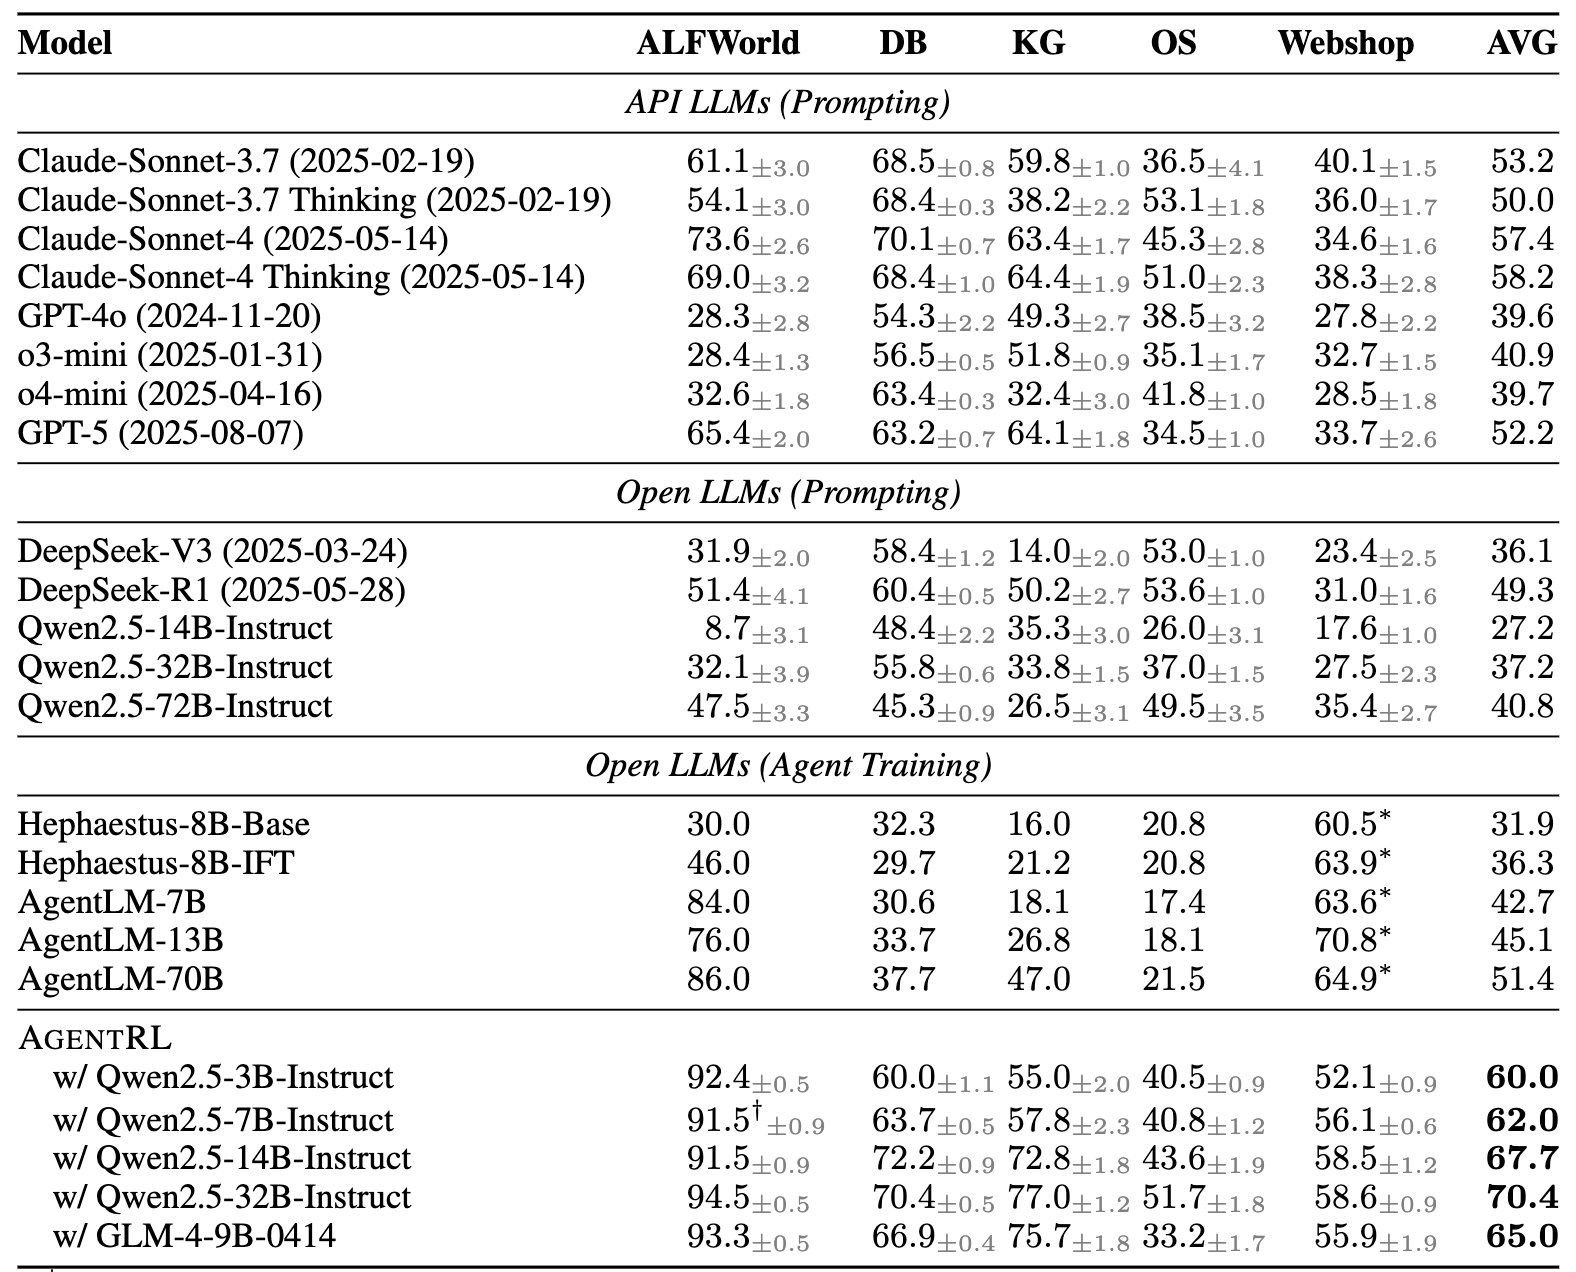
Please see our Leaderboard for full results. Please contact agentbench_fc@googlegroups.com if you have any questions or would like to contribute your results.
🔥[2024.08.13] Introducing VisualAgentBench
VisualAgentBench is designed for evaluating and training visual foundation agents based on large multimodel models (LMMs). We introduce 5 distinct environments spanning
- Embodied: VAB-OmniGibson, VAB-Minecraft
- GUI: VAB-Mobile, VAB-WebArena-Lite
- Visual Design: VAB-CSS
to systematically benchmark 17 LMMs (proprietary & open LMMs). We also provide the trajectory dataset for behavior cloning training on open LMMs for you to develop your own visual foundation agents!
The following is the introduction to the original AgentBench (v0.2).
AgentBench: Evaluating LLMs as Agents
https://github.com/THUDM/AgentBench/assets/129033897/656eed6e-d9d9-4d07-b568-f43f5a451f04
AgentBench is the first benchmark designed to evaluate LLM-as-Agent across a diverse spectrum of different environments. It encompasses 8 distinct environments to provide a more comprehensive evaluation of the LLMs’ ability to operate as autonomous agents in various scenarios. These environments include 5 freshly created domains, namely
- Operating System (OS)
- Database (DB)
- Knowledge Graph (KG)
- Digital Card Game (DCG)
- Lateral Thinking Puzzles (LTP)
as well as 3 recompiled from published datasets:
Table of Contents
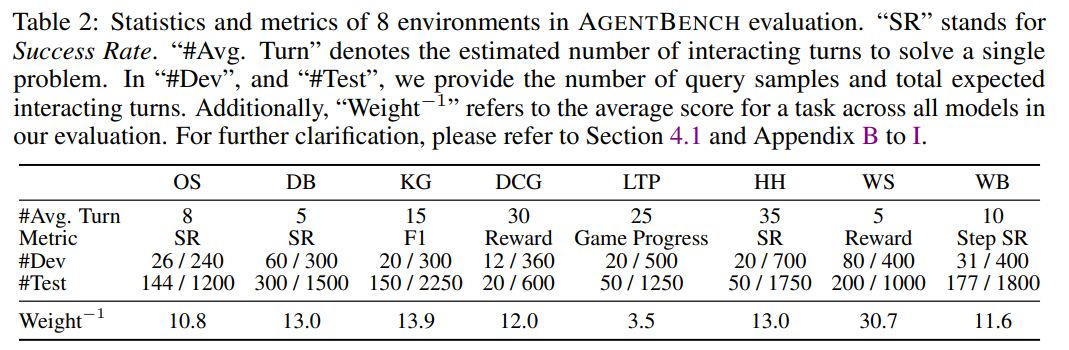
Dataset Summary
We offer two splits for each dataset: Dev and Test. The multi-turn interaction requires an LLMs to generate around 4k and 13k times respectively.
Leaderboard
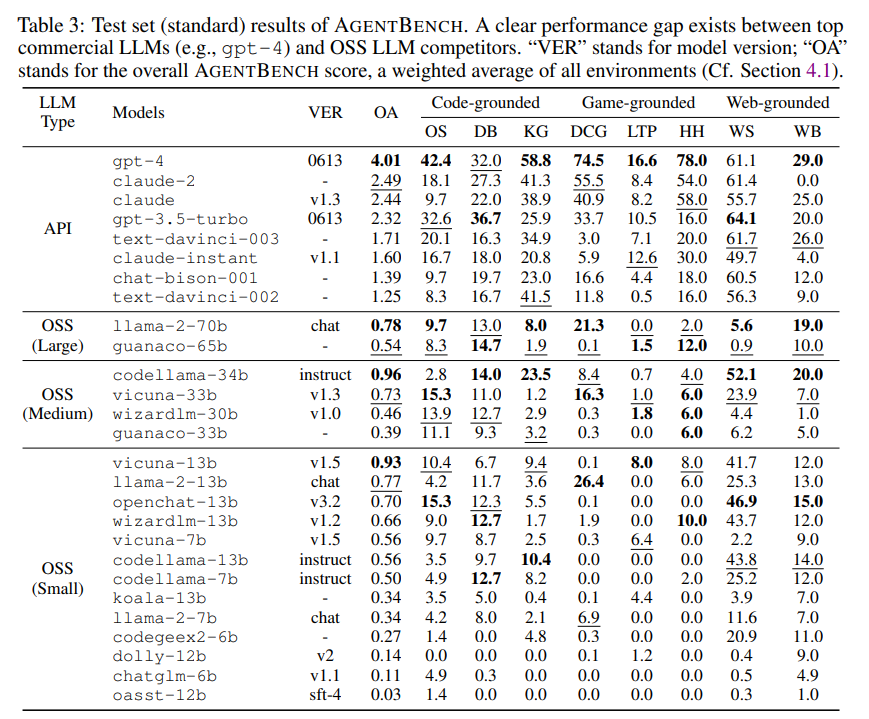
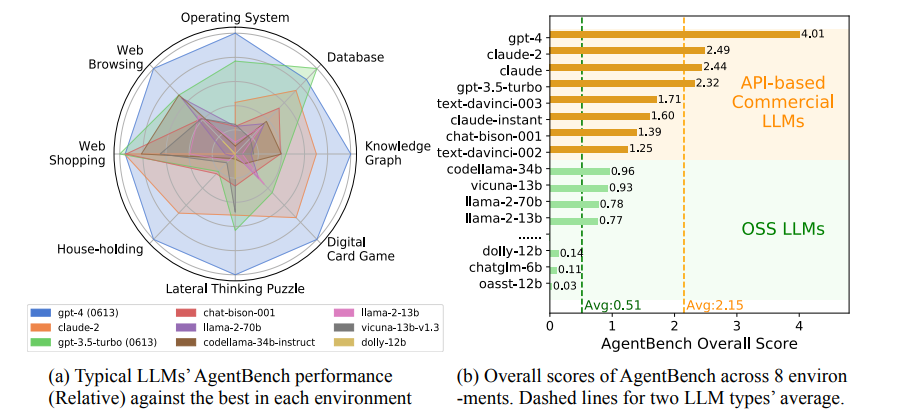
Here is the scores on test set (standard) results of AgentBench.
While LLMs begin to manifest their proficiency in LLM-as-Agent, gaps between models and the distance towards practical usability are significant.
Quick Start
This section will guide you on how to quickly use gpt-3.5-turbo-0613 as an agent to launch the dbbench-std and os-std tasks.
For the specific framework structure, please refer to Framework Introduction.
For more detailed configuration and launch methods, please check Configuration Guide
and Program Entrance Guide.
Step 1. Prerequisites
Clone this repo and install the dependencies.
Python version note: AgentBench pins older scientific Python deps (e.g.
numpy~=1.23.x). Using the recommended Python 3.9 (via conda) is the most reliable way to install dependencies.
cd AgentBench
conda create -n agent-bench python=3.9
conda activate agent-bench
pip install -r requirements.txt
Ensure that Docker is properly installed.
docker psBuild required images for dbbench-std and os-std.
docker pull mysql
docker pull ubuntu
docker build -f data/os_interaction/res/dockerfiles/default data/os_interaction/res/dockerfiles --tag local-os/default
docker build -f data/os_interaction/res/dockerfiles/packages data/os_interaction/res/dockerfiles --tag local-os/packages
docker build -f data/os_interaction/res/dockerfiles/ubuntu data/os_interaction/res/dockerfiles --tag local-os/ubuntu
Step 2. Configure the Agent
Fill in your OpenAI API Key at the correct location in configs/agents/openai-chat.yaml. (e.g. gpt-3.5-turbo-0613)
You can try using python -m src.client.agent_test to check if your agent is configured correctly.
By default, gpt-3.5-turbo-0613 will be started. You can replace it with other agents by modifying the parameters:
python -m src.client.agent_test --config configs/agents/api_agents.yaml --agent gpt-3.5-turbo-0613Step 3. Start the task server
Starting the task worker involves specific tasks. Manual starting might be cumbersome; hence, we provide an automated script.
The assumption for this step is that ports from 5000 to 5015 are available. For Mac OS system, you may want to follow here to free port 5000 to use.
python -m src.start_task -aThis will launch five task_workers each for dbbench-std and os-std tasks and automatically connect them
to the controller on port 5000. After executing this command, please allow approximately 1 minute for the task setup to complete. If the terminal shows ”… 200 OK”, you can open another terminal and follow step 4.
Lite preset (laptops / limited RAM)
If you want to start with minimal concurrency (1 worker per task), use the lite preset:
python -m src.start_task -a --config configs/start_task_lite.yamlStep 4. Start the assigner
This step is to actually start the tasks.
If everything is correctly configured so far, you can now initiate the task tests.
python -m src.assignerIf you started the task server with the lite preset, you can also run the lite evaluation preset:
python -m src.assigner --config configs/assignments/lite.yamlNext Steps
If you wish to launch more tasks or use other models, you can refer to the content in Configuration Guide and Program Entrance Guide.
For the environment of the remaining five tasks, you will need to download the Docker images we provide.
longinyu/agentbench-ltp
longinyu/agentbench-webshop
longinyu/agentbench-mind2web
longinyu/agentbench-card_game
longinyu/agentbench-alfworld
The resource consumption of a single task_worker for the eight tasks is roughly as follows; consider this when launching:
| Task Name | Start-up Speed | Memory Consumption |
|---|---|---|
| webshop | ~3min | ~15G |
| mind2web | ~5min | ~1G |
| db | ~20s | < 500M |
| alfworld | ~10s | < 500M |
| card_game | ~5s | < 500M |
| ltp | ~5s | < 500M |
| os | ~5s | < 500M |
| kg | ~5s | < 500M |
Deploy the KnowledgeGraph service loacally
the KnowledgeGraph task depends on an online service which now is not stable, if you want to deploy the service locally, you can follow steps below:
step1. download the database and setup the service freebase-setup.
step2.
change this line sparql_url: "http://164.107.116.56:3093/sparql" to sparql_url: "<your service api of sparql>" in /configs/tasks/kg.yaml.
P.S. you should start your KG service before you start the agent tasks services.
Extending AgentBench
If you wish to add new tasks to AgentBench, you may refer to Extension Guide.
References
Avalon task is merged from AvalonBench, which implements a multi-agent framework.
Other options in Benchmarks & Datasets
 promptfooObservability
Test cases are YAML: a prompt, some inputs, and assertions about the output. That is enough to produce a side-by-side matrix comparing several prompts or models on the same inputs, and to fail a build when a change makes things worse. The same tool also attacks the application, generating adversarial inputs to surface vulnerabilities and compliance risks. It works from the outside — prompt in, answer out — so when the question is which step inside a running agent went wrong, this is not the instrument for it.
 DeepEvalObservability
The shape is deliberately pytest's: assertions inside test functions, a runner that discovers them, parameterised cases — except the assertion is about whether an answer was faithful to its context or whether an agent finished the task. That framing is the point, because it puts quality regressions in front of the same gate that catches syntax errors. The thing to plan for is that most of these metrics are scored by a model, so the suite has a bill and a variance that ordinary tests do not.
 camelOrchestration
CAMEL's core idea is agents talking to each other: a RolePlaying session pairs an AI user that issues instructions with an AI assistant that carries them out, and a Workforce hands split-up subtasks to workers under a coordinator. Around that sit eighty-odd toolkits, around fifty model backends, benchmark harnesses such as GAIA and BrowseComp, and pipelines that turn the resulting conversations into fine-tuning data. That breadth is the point if you are running experiments; if you only want one dependable agent in production you will carry a great deal you never use, and the library has been public since 2023 yet is still on 0.2.x.